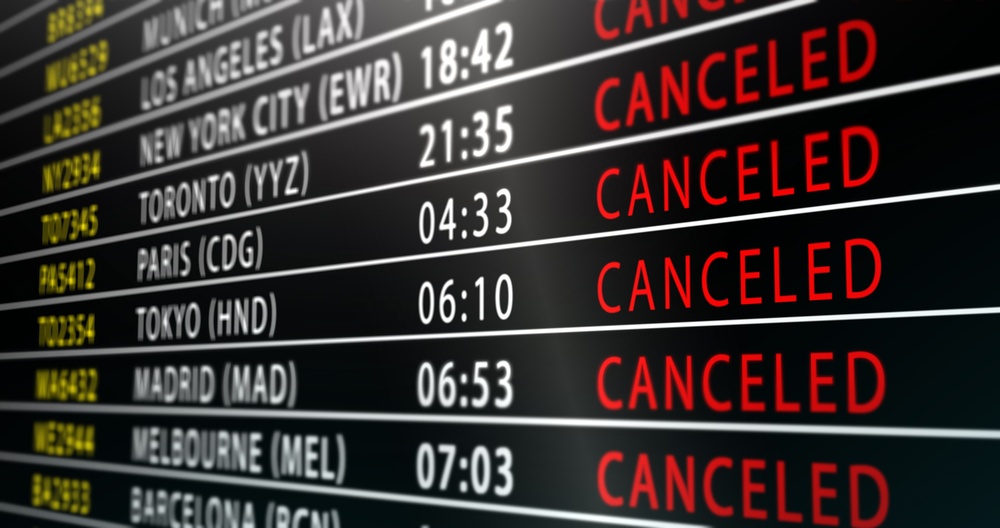
There is a cruel irony in sitting on an airport floor watching departure boards turn into a sea of red cancellations due to key systems not working when your agenda for the week is wall-to-wall database high availability.
Instead of debating synchronous vs asynchronous replication, DR strategies, and connection routing over stroopwafels at Percona Live, I spent hours watching the UK air traffic control infrastructure demonstrate in real time what happens when systems fail.
When central flight processing systems fail, planes don’t fall out of the sky… human operators manually step down capacity to preserve safety. That’s good engineering for avionics. But from an operational and user standpoint, throughput immediately collapses to zero.
In data infrastructure, we don’t have the luxury of grounding transactions.
The Anatomy of a Single Point of Failure
A system can have redundant hardware racked across three availability zones, dual power supplies, and expensive vendor contracts. Yet, if all traffic funnels through a single state coordinator, a centralized configuration ingest pipeline, or a shared control plane, you don’t have a distributed system, you have an expensive distributed single point of failure (SPOF).
When flight processing pipelines choke on malformed inputs or centralized state divergence, both primary and secondary nodes often trigger safe-mode lockouts simultaneously. In our world, that’s equivalent to:
- A split-brain scenario where two primary database nodes lock tables or drop out of quorum to prevent data corruption.
- A health-check orchestrator misidentifying network latency as a total failure and flapping primaries until connection pools exhaust.
- A backup cluster that faithfully replicates corrupted metadata or poison-pill transactions within milliseconds.
Redundancy is merely having two of something. Resilience is knowing the backup won’t trip over the exact same rake.
What Real HA Demands
If your system cannot survive the abrupt death of its primary path without manual human intervention at 2:00 AM, you do not have High Availability. You have an alerting system attached to an anxious engineer.
- Quorum-Based Consensus Over Brittle Primaries: Systems relying on simple active/passive replication with manual DNS failover are an invitation to downtime. Modern clustering (whether using Galera, group replication, or consensus protocols like Raft/Paxos) requires odd-numbered nodes and a quorum to ensure automated, safe leader election without split-brain.
- Smart Traffic Decoupling: Applications should never point directly to a database node’s hardcoded IP. Layer 7 proxies, intelligent connection pools (like ProxySQL), and virtual IPs isolate application clients from infrastructure churning underneath. If Node A dies, Node B takes the writes, and the application experiences a momentary sub-second reconnect rather than a total outage.
- Isolated Failure Domains: True HA isolates inputs. If a poison-pill query or malformed configuration packet enters the system, it must be quarantined. If the primary node crashes on execution, failover shouldn’t automatically replay that exact fatal query against the standby node and take down the entire cluster.
- Drills Over Documentation: If you haven’t tested automated failover under synthetic network partitions and heavy load, your failover plan is just a hypothesis.
Wrapping Up
Missing the hallway track and live demos in Amsterdam stings. But staring at a stalled airport terminal provided the starkest reminder imaginable: downtime is never just an abstract metric on a Grafana dashboard. It leaves real people stranded, operations halted, and trust burned.
Design for failure. Automate your recovery. Test your clusters.
Author: Aaron West, Sales Engineer at SIOS